vibe-openscad

bare-ctx32k/qwen3-8b / tier-2-hex-bolt

success tier 2

bare (qwen3-8b)

render
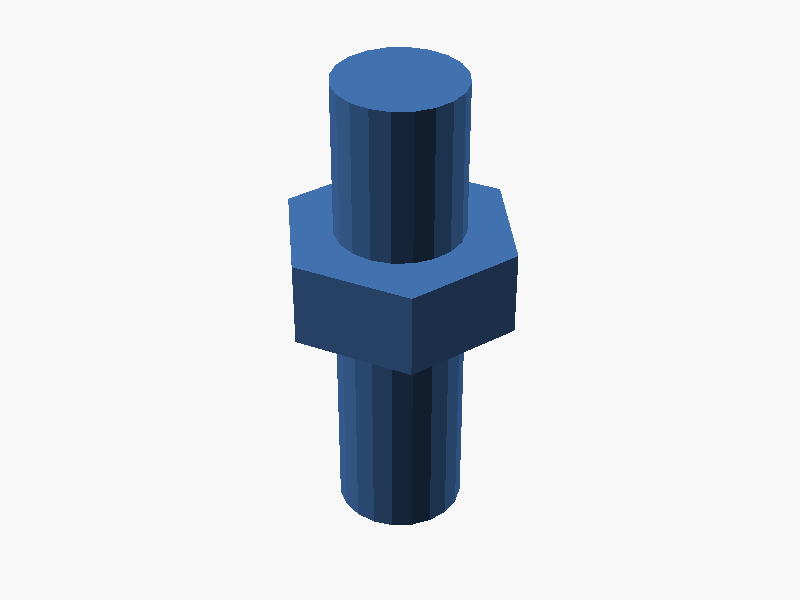
bare render of tier-2-hex-bolt
loading STL…
success 66.6s · 216/6458t
SCAD (18 lines)
r = 13 / sqrt(3);
head_height = 5.3;
shaft_radius = 4; // diameter 8mm
shaft_length = 30;

union() {
    linear_extrude(height=head_height, $fn=6)
        polygon(points=[
            [r, 0],
            [r * cos(60), r * sin(60)],
            [-r * cos(60), r * sin(60)],
            [-r, 0],
            [-r * cos(60), -r * sin(60)],
            [r * cos(60), -r * sin(60)]
        ]);
    translate([0, 0, -15])
        cylinder(r=shaft_radius, h=shaft_length, $fn=20);
}
パラメータ (3) —
スライダを動かすと openscad-wasm で再レンダリング

meta

runIdbare-ctx32k_qwen3-8b-566165c1e124-2026-09-05T17-50-54-817Z
matrixIdbare-ctx32k/qwen3-8b
signature566165c1e124c1f2…
provideropenai-self-hosted
modelqwen3-8b
harnessbare
statussuccess
duration66.64s (wallclock: load + prompt eval + generation + network)
TTFT0.107s
generation time65.90s (pure decode, excludes load + prompt eval)
tokens216 in / 6458 out
generation tok/s98.0 tok/s (pure decode rate)
wallclock tok/s96.9 tok/s (end-to-end)
createdAt2026-09-05T17:50:54.817Z
gitCommit39080c1672b0
openscadOpenSCAD version 2026.04.27

model metadata (self-hosted)

セルフホスト LLM はクラウドの単一 provider と違い、 実質「(モデル開発者, weight publisher, 量子化)」の組で挙動が決まる。 run 時に LM Studio / Ollama から取得した値:

publisherlmstudio-community
typellm
archqwen3
quantizationQ4_K_M
max ctx32,768 tok
capabilitiestool_use
host GPUNVIDIA GeForce RTX 3090 (Vulkan)
host VRAM24 GB
host CPU12th Gen Intel(R) Core(TM) i9-12900K
host RAM32 GB

prompt

OpenSCAD で、規格に準じた M8 サイズの六角ボルトを作ってください。
ねじ山自体は省略してよく、円柱のシャンクで構いません。

寸法は以下に従ってください:
- 頭部は六角柱で、対辺距離(across-flats)13mm、高さ 5.3mm
- シャンク(軸部)は直径 8mm、長さ 30mm の円柱
- ボルト全体の中心軸は +Z 軸方向
- 頭部の底面が原点(z=0)に来るように配置し、シャンクは z<0 側へ伸ばす

完成したコード全体を ```openscad ... ``` のフェンスで囲んで出力してください。コードのみで、追加の説明は不要です。